

At first glance, language might seem like a straightforward system of symbols and rules. But consider this: how do you know that a hot cup of coffee can burn you, while a hot new song cannot? Or understand that heavy rain might ruin a picnic, but heavy thoughts won’t crush your brain? This immediate, almost effortless comprehension highlights a crucial truth about language: it’s deeply intertwined with our knowledge of how the world works.
This connection between words and reality has posed one of the greatest challenges in artificial intelligence. While it’s largely up for debate whether large language models have a so-called “world model”, or innate understanding of the world and its properties, what is known is how natural language works. Moreover, we know what it means to effectively understand language as well.
In our last article, we learned how LLMs “learn” language.

Now, it’s time to wrap together our grasp of how LLMs work by discussing language from a more theoretical level.
We’ve seen how intelligent systems—biological and artificial alike—have an incredible capacity to learn and produce language. So that begs the question: what, in fact, does it actually mean to understand language? Let’s start with a discussion on the complexities of natural language understanding.
Why Language Understanding is Complex
Read through this famous sentence from linguist and O.G. cognitive scientist Noam Chomsky: “Colorless green ideas sleep furiously.”
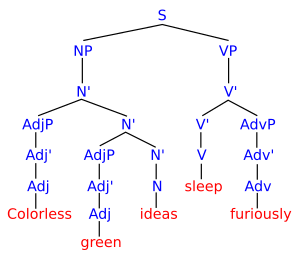
At first glance, it might seem perfectly normal—after all, it follows English grammar flawlessly. It has two appropriate adjectives modifying a noun, followed by a verb and an adverb, just as you might find in “Happy young children play enthusiastically.” Yet while one sentence makes perfect sense, the other is pure nonsense.
This example reveals something profound about language understanding. Getting the grammar right is only the beginning. “Colorless green” is a contradiction—nothing can simultaneously have no color and be green. “Ideas” are abstract concepts; they can’t perform physical actions like sleeping. And how exactly does one sleep “furiously”? Each piece of the sentence violates our fundamental knowledge about how the world works.
The complexity deepens when we consider that the same words can mean entirely different things depending on context. “The bank is steep” could refer to a financial institution’s harsh policies or to the challenging slope beside a river. A “bright student” isn’t actually glowing, and a “heavy discussion” has no physical weight. Understanding these distinctions requires not just knowing words and their relationships, but understanding contexts, implications, and real-world meanings.
This reveals why true language “understanding” is so challenging for artificial systems. While it’s easy to learn the statistical patterns of language—which words tend to follow others, which concepts frequently appear together—mastering the deeper understanding of language that humans take for granted is a whole different problem altogether.
This gap between pattern recognition and true understanding lies at the heart of the language comprehension challenge. To truly understand language, a system needs more than purely grammatical and lexical knowledge—it needs to grasp how language connects to the real world, how concepts relate to each other, and how cause and effect work in physical and abstract domains alike.
In other words, intelligent systems learn a set of linguistic regularities that enable them to “understand” language.
Learning From Regularities
Language comprehension emerges from three implicit rulesets or regularities. A regularity is a pattern that occurs with some consistency or predictability, but that pattern might not be explicitly definable. In language, there are several key types of regularities. First, there’s grammar—the rules that determine how words can be combined into meaningful sentences. Then there are topical relationships—the networks of concepts that naturally occur together, like “lawyer,” “court,” and “judge.” Finally, there are cause-and-effect relationships that reflect how things work in the real world—why rain leads to wet ground, or why hunger makes us seek food.
Let’s dive deeper into each of these three regularities.
Grammatical Regularities
Grammar represents one of the most fundamental patterns in language - the rules governing how words can be combined to form meaningful phrases and sentences. But what makes grammatical regularities particularly interesting is that they emerge naturally from language use, rather than being solely dictated by formal rules.
Consider what happens after you see or hear the word “the.” Your mind automatically expects either an adjective or a noun to follow—“the red car,” “the lawyer,” “the bright sunny day.” You’d be surprised to encounter “the sleep” or “the quickly.” This expectation isn’t just about following textbook rules; it’s a deep pattern recognition that develops through exposure to language. Similarly, after “may,” you anticipate a verb or adverb—”may go,” “may quickly decide”—but not a noun.
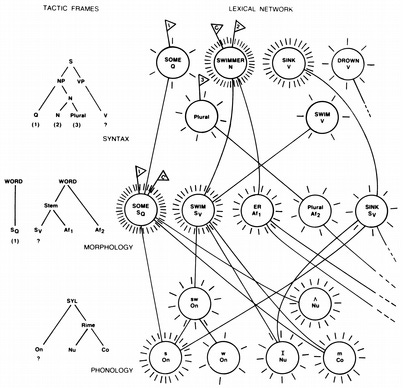
These grammatical regularities operate through a process cognitive scientists call “priming,” where exposure to one word automatically prepares our minds for related possibilities. When you encounter the word “the,” it activates a network of potential continuations, with adjectives and nouns receiving the strongest activation. This process is part of a broader phenomenon called “spreading activation,” where the activation of one concept automatically flows to related concepts in our mental network. After “may,” activation spreads primarily to verbs and adverbs; after “very,” it spreads to adjectives and adverbs.
This automatic spreading of activation explains why we can process language so quickly and why grammatical violations feel immediately jarring—they interrupt the expected flow of activation through our linguistic networks. The strength of these activation patterns also explains why we can often predict the grammatical category of the next word in a sentence even if we don’t know exactly what word it will be.
What’s fascinating about grammatical regularities is how they interact with meaning. While they can operate independently of semantics (as demonstrated by “colorless green ideas sleep furiously”), they typically work in concert with meaning to create understanding. A sentence like “The dog bit the man” is instantly recognizable as different from “The man bit the dog,” not just because of word order rules, but because these rules help us understand who did what to whom.
This intricate system of patterns helps explain why language models can often produce grammatically correct sentences even when the meaning is nonsensical. The patterns of grammar are more consistent and easier to learn than the patterns of meaning—but as we’ll see, grammar alone is insufficient for true language understanding.
Topical Regularities
Language exhibits strong patterns in how words cluster together by topic or domain. Think about legal language: when you encounter the word “lawyer,” you’re likely to see terms like “court,” “judge,” “client,” and “case” nearby. Or in a medical context, “diagnosis” naturally occurs with “symptoms,” “treatment,” and “patient.” These aren't just random co-occurrences—they reflect meaningful relationships between concepts that tend to be discussed together.
These topical relationships form rich semantic networks. A word like “bank” has different clusters of associated terms depending on whether it’s being used in its financial sense (money, account, deposit) or its geographical sense (river, shore, steep). These associations are so strong that encountering just one or two words from a cluster often lets us predict what topic is being discussed and what other related terms might appear
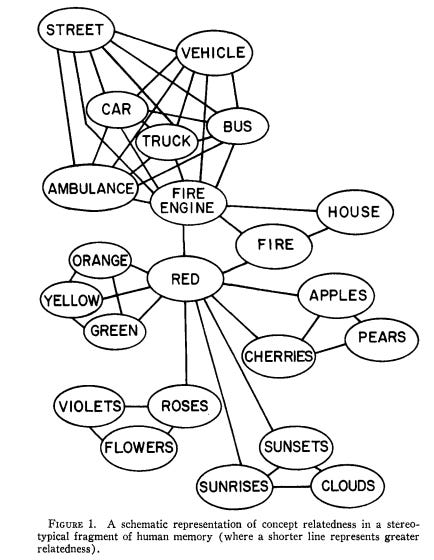
Returning back to the concept of “priming” and spreading activation, these topical relationships explain why certain words rapidly bring related concepts to mind. When you read “red,” your brain doesn’t just activate that single word—it primes a whole network of related concepts like “roses” and “fire engine”, which then leads to more activations later on with additional context.1 This spreading activation makes it easier to process related words that appear next, and harder to process unrelated ones. It’s why we can quickly detect when something seems “off” in a sentence—the activated semantic network clashes with the actual words we encounter.
Topical regularities can be subtle and context-dependent. While “hot coffee” and “hot topic” both use the same adjective, they draw from entirely different semantic fields. Understanding these nuances requires recognizing not just which words commonly appear together, but how their meanings shift and combine in different contexts. This is why literal translations often fail—the topical (or grammatical) associations that make sense in one language might be completely different in another.
This layered system of word associations and semantic relationships helps explain how we can rapidly understand meaning in context. When we encounter a word like “court,” the surrounding words quickly disambiguate whether we’re reading about basketball, law, or royalty. These topical patterns provide crucial cues for understanding, but they must work in concert with grammatical structure and cause-effect relationships to create true comprehension.
Cause-effect and Inferential Regularities
The ability to understand language goes far beyond recognizing word patterns or topic clusters—it requires grasping how events and concepts logically connect to each other. When we read “Dark clouds gathered overhead, so Sarah grabbed her umbrella,” we immediately understand the unspoken causation. No one needs to explicitly state that dark clouds often bring rain, or that umbrellas keep people dry.
These cause-effect relationships appear throughout language in various forms. Sometimes they’re marked explicitly with words like “therefore,” “because,” or “consequently.” Other times, they're implied through simple narrative progression, i.e. “John hadn't eaten all day. He felt dizzy.” Though there's no explicit causal marker, we instantly understand that the hunger caused the dizziness. This kind of inference requires not just recognizing words, but understanding how events and states relate to each other in the real world.
Language is filled with these inferential leaps. When we read “The ice cream melted,” we automatically understand that it must have been warm, even if temperature was never mentioned. If we're told “Lisa rushed to catch the bus,” we can infer she was running late, wanted to arrive somewhere at a specific time, and knew the bus operated on a schedule—all from a simple six-word sentence.
This network of cause-effect relationships extends beyond physical causation into social, emotional, and abstract domains. We understand that insults can cause anger, that studying typically leads to better test performance, and that economic policies can affect market behavior. These relationships form a complex web of understanding that helps us make sense of everything from simple sentences to complex narratives.
Regularities and LLMs
Remarkably, modern large language models have demonstrated an incredibly ability to capture each of these aforementioned regularities. Through exposure to vast amounts of diverse text, these systems implicitly learn relationships between words and phrases at scale.
Grammatical regularities emerge naturally from the statistical patterns of word sequences. By seeing millions of examples of how words combine in sentences, LLMs learn that articles are typically followed by nouns or adjectives, that subjects and verbs must agree in number, and that certain words can only appear in certain syntactic positions. This explains why they can reliably complete sentences with grammatically correct continuations and even generate syntactically valid but semantically nonsensical sentences like Chomsky’s famous example.
Topical regularities are captured through the co-occurrence patterns of words across contexts. Through their training, these models learn that words like “court,” “judge,” and “lawyer” frequently appear together in legal contexts, while “court,” “shoot,” and “pointguard” cluster in basketball-related texts. This allows them to maintain topic coherence in generation and to disambiguate word meanings based on surrounding context.
Perhaps most surprisingly, LLMs also appear to capture many cause-effect relationships, despite never directly experiencing the physical world. They learn that “dark clouds” are associated with rain, that hunger leads to specific physical symptoms, and that certain actions typically produce certain consequences. This knowledge comes purely from seeing how events and states are described as following each other in text, allowing the models to make many of the same inferential leaps that humans do.
The purely text-based learning approach inherent to the development of LLMs has important limitations, however. Without grounding in real-world experience, the models’ understanding is arguably superficial—they know that fire is associated with heat and burning, but don't truly understand what heat feels like or why burning is dangerous. They can mimic understanding through pattern recognition, but lack the deep causal knowledge that comes from actually experiencing and interacting with the world.
This reveals both the power and limitations of learning language through statistical patterns alone. While it can take us remarkably far, true understanding likely requires something more: a connection to real-world experience and causality that goes beyond what can be learned from text alone.
In the next (and final) article in this series, we’ll investigate arguably the hottest topic in AI and cognitive science today: do LLMs understand what they say? You might be surprised by some potential approaches and answers to this question, so make sure to stay tuned!
To dive deeper into this topic, check out Khan Academy’s great explainer video: https://www.khanacademy.org/science/health-and-medicine/executive-systems-of-the-brain/cognition-lesson/v/semantic-networks-and-spreading-activation