

You type in a question, hit send, and within seconds, you receive a coherent, thoughtful response. Interacting with large language models (LLMs) like ChatGPT feels almost magical, doesn't it? But as author Arthur C. Clarke famously said, “Any sufficiently advanced technology is indistinguishable from magic.” Today, we're going to peek behind the curtain and demystify this “magic.”
What if I told you that at its core, this seemingly intelligent behavior boils down to an incredibly sophisticated guessing game? A game where the AI predicts, with astonishing accuracy, what word should come next in a sequence. It's a simple concept with profound implications, and it's the foundation of how LLMs like ChatGPT produce text.
The Core Function: Prediction
Today’s most sophisticated language models like ChatGPT view natural language as a “sequence” of words or phrases. At their heart, LLMs are sophisticated sequence prediction engines, and their primary function is to predict the next most likely piece of text given a sequence of preceding text. This prediction capability is the foundation upon which all their seemingly complex behaviors are built.
It's important to note that models like GPT-3.5/4 and other “chat” models have been fine-tuned to behave “interactively,” enhancing their ability to engage in dialogue-like interactions. So, even though it might not feel like they’re simply predicting the next element in a sequence but rather generating brand-new text, the underlying mechanism remains prediction-based.
Tokenization
How does the language model predict what comes next in a sentence or paragraph? The journey begins when we feed a sequence of “tokens” into an LLM. Tokens are the fundamental units that the model works with—tokens are typically words or parts of words, sometimes even individual characters, depending on the model's design. For instance, the word “tokenization” might be broken down into tokens like “token,” “ization,” or even smaller units.
Once the input text is “tokenized”, each token is converted into a numerical representation, typically a high-dimensional vector. These vectors capture not just the identity of the token, but also encode subtle aspects of its meaning and usage based on the model's training.
Turning natural language into these numerical representations is a critical aspect of what enables machines to “learn” language—it enables them to handle language symbolically, akin to how our own cognitive processes do in our brain.
“Deep” Learning
Large language models are considered “large” for two main reasons:
They are trained on massive amounts of data.
They consist of billions of artificial “neurons” that process different aspects of the data.
Let’s focus on the second “large” aspect of LLMs. These billions of neurons are organized into different layers that feed into one another—this is what forms a “neural network”.
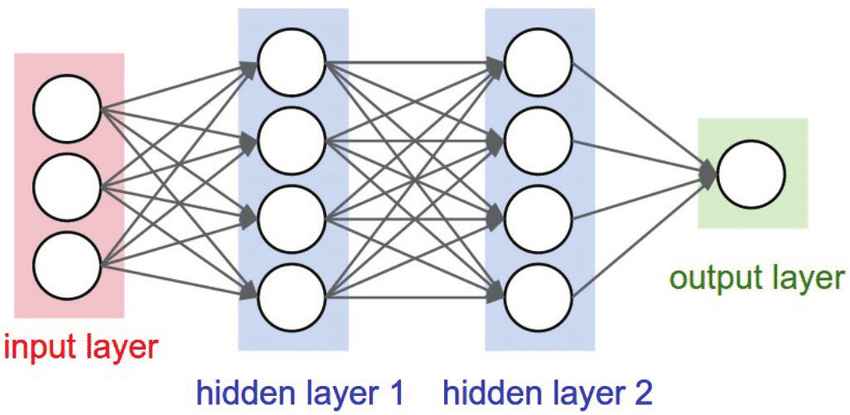
Here’s a visualization of a rather simple neural network, with just 3 layers before the output and only a few neurons. Imagine scaling this up to the level of billions of neurons, and you can truly see how “large” these systems get.
One interesting observation about these neurons is that they each tend to focus on specific aspects of language—in other words, they “specialize” in specific features, much like how biological neurons also undergo specialization to excel at different tasks. Anthropic, one of the leading AI research startups, conducted research in which they pinpointed exactly which linguistic features “activated” individual neurons, and mapped it out in an interactive graph.
As the input passes through the model's layers, it's continually refined and transformed. The model is essentially asking itself at each step: “Given everything I've seen so far, what's most likely to come next?” This process culminates in the final layer, where the model produces a probability distribution over its entire vocabulary.
Probability Distribution
These probabilities represent the model's best guess at what should come next in the sequence. High probabilities indicate tokens the model thinks are very likely to follow, while low probabilities are assigned to tokens the model deems unlikely in this context.
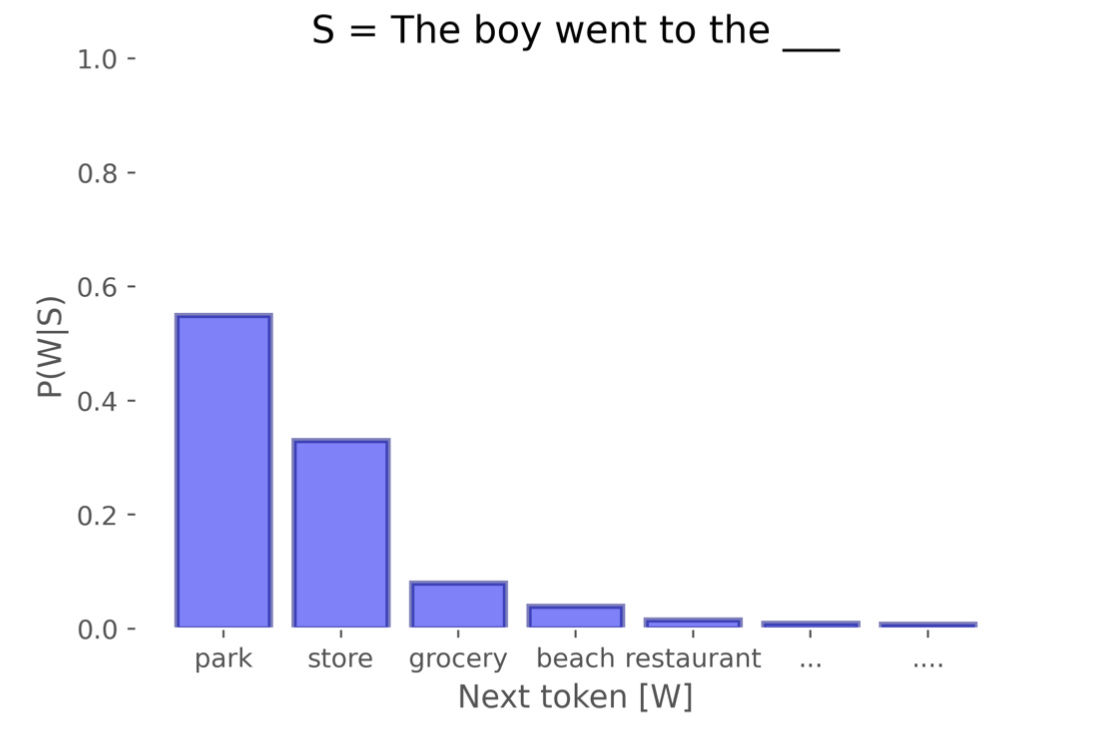
This is an example of what the probability distribution could look like for predicting the next word in the sentence, “The boy went to the …”. In this example, “park” is the token with the highest probability, so it would be the token the language model would predict next in the sequence.
This process of predicting and selecting the next token repeats over and over again, until one of two things occurs:
The LLM runs out of context (i.e., the response becomes too long!)
or, more likely, the LLM predicts a “stop” token.
When the LLM predicts a “stop” token, this tells it that it has completed generating a response. This is how ChatGPT knows when to end its reply—the reason its responses often end with a question (like “Would you like me to further explain ____?”) is because the program has been fine-tuned to predict the “stop” token after these sorts of questions. Without it, it would continue generating tokens until it reaches its the maximum of its “context window,” or how many tokens it can process at once.
Are LLMs Deterministic or Stochastic?
A common misconception about LLMs are that they are either deterministic or stochastic—that is, whether they always produce the same output given the same input, or whether an element of randomness or unpredictability is involved.
Given the aforementioned explanation on how LLMs are sequence predictors that operate off of statistical probability distributions, you might be inclined to say that they are indeed deterministic. But if you’ve used ChatGPT, you’ve probably seen that giving it the same input rarely results in the exact same output each time, which would imply LLMs are stochastic.
In reality, LLMs leverage a combination of deterministic and stochastic processes.
The core architecture and processing of an LLM is deterministic. Given the same input and the same model parameters, an LLM will always produce the exact same probability distribution for the next token. For instance, every time you input “The capital of France is” into the same LLM, it will generate the identical probability distribution for the next token, with “Paris” likely having the highest probability.
However, the process of actually generating text introduces a stochastic element. When the model selects the next token based on the probability distribution it has generated, it uses a sampling method that introduces randomness, which is why you can get different completions even with the same prompt. These sampling methods allow for variety and “creativity” in the generated text, preventing the model from always producing the same output for a given input.
We can even encourage higher levels of stochasticity by tweaking parameters, such as:
Temperature: how random the selection from the probability distribution is. Lower temperature results in a more deterministic selection, whereas higher temperature results in more randomness.
Top-K Sampling: considering only the k most likely next tokens and sampling from those. Increasing K increases the chance that a less-probable token is selected, and vice-versa.
Nucleus (Top-P) Sampling: Considering the smallest set of tokens whose cumulative probability exceeds a threshold P. Decreasing P increases the chance that a less-probable token is selected, and vice-versa.
Furthermore, the limits of computational power and inherent universal entropy make the probability distribution not truly deterministic. In reality, hardware is not perfect, and as much as we try, computationally-intensive programs like LLMs will never be wholly closed systems. We might never realize these imperfections in our day-to-day lives with the programs we run, but remember that LLMs run complex mathematical operations to the scale of billions of individual neurons—slight imperfections are bound to arise.
TL;DR: Large Language Models (LLMs) generate text through a sophisticated process of sequence prediction. Here's how it works:
Input text is broken into tokens (words or word parts).
Tokens are converted to numerical vectors.
These vectors pass through multiple neural network layers.
The model predicts probability distributions for the next token.
A token is selected based on this distribution, often with some randomness.
This process repeats, generating text token by token, until completion.
LLMs combine deterministic processing with stochastic selection, allowing for both consistency and creativity in output. Although they operate on simple principles of statistical prediction, they are able to produce complex human-like text.
We've delved into how LLMs produce text, but there's another equally fascinating aspect of these models that we haven't yet explored: how they “learn” language in the first place. The training process that enables these models to capture the intricacies of human language is a complex and computationally intensive journey, involving massive datasets and sophisticated learning algorithms.
In the next article, we'll examining how LLMs are trained, the data they learn from, and the techniques used to endow them with their seemingly vast knowledge of language and the world.
brilliant